Enterprise LLM Development Company
We engineer enterprise-grade LLMs based on how your business actually works, using your data, terminology, and requirements rather than generic models. From model selection and fine-tuning to secure deployment and evaluation, our enterprise LLM development company ensures every AI system we deliver keeps your data, models, and AI capabilities under your control.
Software Products Shipped To Production
Years Building Enterprise Software
Continents Served With Dedicated AI Pods
AI Deployments


- Choose the model that fits your business use case
- Fine-tune models with your proprietary enterprise data
- Deploy on your cloud, on-premise, or sovereign environment
- Evaluate, secure, and guardrail models before production
- Integrate LLMs with your enterprise systems and data


Why the Model Layer Matters Before You Build Anything On Top
An LLM powers every copilot, AI agent, and RAG system. Get the model layer wrong, and problems compound upward.
01
Right Model For The Job
The biggest, most expensive model is not always the right choice for every workload. Our team matches model size, cost, latency, and performance based on the actual requirements.
02
Trained On Your Business Language
We fine-tune models on proprietary data using your documents, tickets, and domain terminology, so the outputs reflect how your business communicates and operates.
03
Deployed Where Your Data Must Stay
Our experts deploy models on your infrastructure, in a dedicated cloud, or within an on-premises environment, based on your security, data residency, and sovereignty requirements.
04
Evaluated Before It Ships
We ensure that every model we deploy is benchmarked, red-teamed, and tested to identify hallucinations, weaknesses, and risks before it reaches a live production workflow.
05
Everything Else Builds On This
Copilots, AI agents, and retrieval-augmented generation (RAG) systems depend on a reliable model layer. We build the right foundation before building what comes next.
Proprietary Data Fine-Tuning
Models are adapted using proprietary business data, domain knowledge, and terminology, not generic public datasets.

Benchmarked and Red-Teamed
Every model is evaluated and stress-tested to identify reliability issues and potential risks before deployment.

Enterprise Engineering Experience
Built on more than 15 years of experience delivering complex software and enterprise technology solutions.

Enterprise LLM Development Services for Growing Teams
Six ways EWW builds the model layer your AI systems run on, matched to your workload, data and compliance needs.
Model Selection & Strategy
Our LLM engineers benchmark every major model family, proprietary and open-weight, matching your enterprise workload with the right model for performance, cost, context length, security, and scalability.
Fine-Tuning
Our AI team fine-tunes foundation models based on proprietary enterprise data, terminology, and workflows using LoRA and full fine-tuning, so every output reflects how your enterprise actually communicates.
Secure Deployment & Hosting
We deploy your AI models to the cloud, a private VPC, or fully on-prem environments, with our engineering team addressing data residency, security, sovereignty, and industry compliance requirements.
Evaluation & Guardrails
Our LLM experts benchmark every AI model against business-specific criteria and red-team models for jailbreaks and hallucinations, helping enterprises establish reliable outputs, safety controls, and governance.
Prompt & Context Engineering
Our AI engineers design prompts, system instructions, and context strategies around enterprise workflows to deliver the right information at the right time, reduce unnecessary tokens, and make LLM applications more reliable.
Monitoring & Optimization
We constantly monitor enterprise LLM performance, latency, usage, drift, and output quality after launch, then retune or retrain models as your enterprise data, workflows, and usage patterns evolve.
Where Enterprise LLM Projects Go Wrong
The model is rarely the problem. It is usually model choice, data readiness or evaluation skipped under deadline pressure.
| Challenge Area | The Problem | The Solution | ||
|---|---|---|---|---|
|
Model Choice
|
The Problem | Teams choose the biggest model for every workload, then get blindsided by increasing costs and latency without improving task outputs. | The Solution | We match every workload to the right model, so routine tasks run on smaller, cheaper models, and only complex tasks run on stronger, more expensive models. |
|
Data Readiness
|
The Problem | Fine-tuning often begins with messy, unlabeled, or inconsistent data, and the customized model can perform worse than the base model it replaced. | The Solution | Our AI team audits and structures your data before fine-tuning. This gives the model a cleaner foundation to learn your domain, not your data’s mess. |
|
Evaluation
|
The Problem | A model reaches production without adversarial testing, and the first hallucination or jailbreak appears in front of a real customer. | The Solution | Our team red-teams and benchmarks each model against real-world edge cases. We apply output guardrails before the model enters a live workflow. |
|
Cost & Latency
|
The Problem | After model launch, no one monitors cost and performance. As a result, token spend and latency can drift for months before anyone notices. | The Solution | We set up monitoring for cost, latency, and output quality from the beginning. Our team establishes clear ownership and sets a schedule for model retraining. |
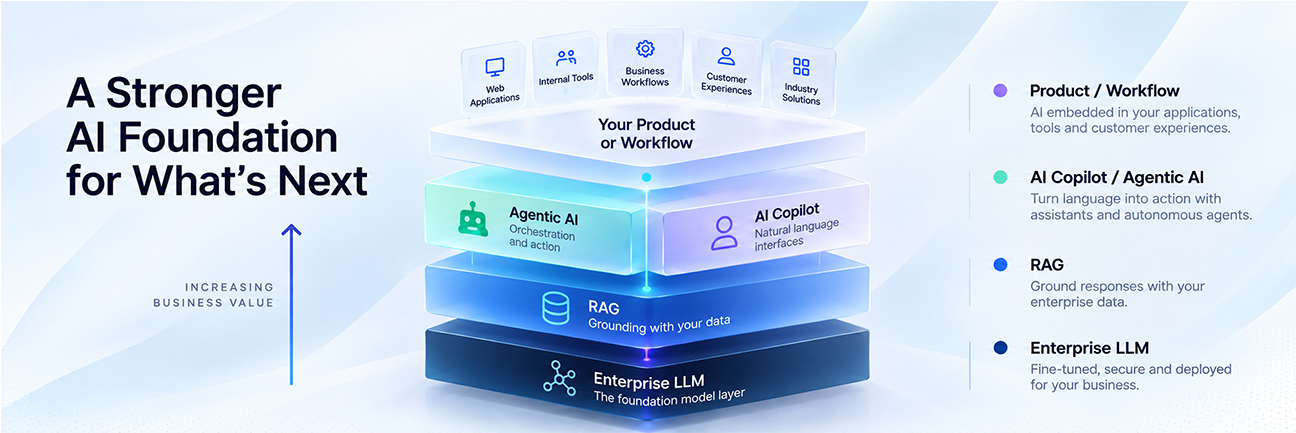
Enterprise LLM Solutions by Architecture and Deployment
Our enterprise LLM development solutions combine deployment environments and model architectures, matched to your data, security, cost, latency, and operational requirements, not applied as a default.
Cloud-Hosted LLM
- Fastest path to production deployment
- Scales automatically with usage spikes
- Lowest upfront infrastructure investment
- Access to the latest models as they become available
- Best suited for workloads without strict data restrictions
Private VPC-Hosted LLM
- Model runs within your private cloud environment
- Data remains within your network boundary
- Supports enterprise security and access policies
- Gives greater control over infrastructure and networking
- A strong fit for regulated and security-sensitive workloads
Sovereign / On-Prem LLM
- Full control over infrastructure and enterprise data
- Supports strict data residency and sovereignty requirements
- Keeps sensitive workloads within approved environments
- Backed by dedicated infrastructure and operational expertise
- Built for government and defense client
Fine-Tuned Domain LLM
- Adapted to your domain, terminology, and business workflows
- Improves performance on specialized enterprise tasks
- Reduces prompt complexity and repeated context
- Requires clean and relevant training data
- Updates as business knowledge and requirements evolve
Multi-Model Routing
- Routes each workload to the best-fit model
- Controls costs by reducing unnecessary flagship model use
- Supports fallback when a model or provider becomes unavailable
- Reduces dependency on a single model provider
- Balances performance, cost, and reliability across workloads
Small Language Models (SLMs)
- Lower operating costs for narrow, repetitive workloads
- Lower latency for time-sensitive use cases
- Supports edge and on-device deployments for suitable workloads
- Easier and faster to adapt for specialized tasks
- Works alongside larger models
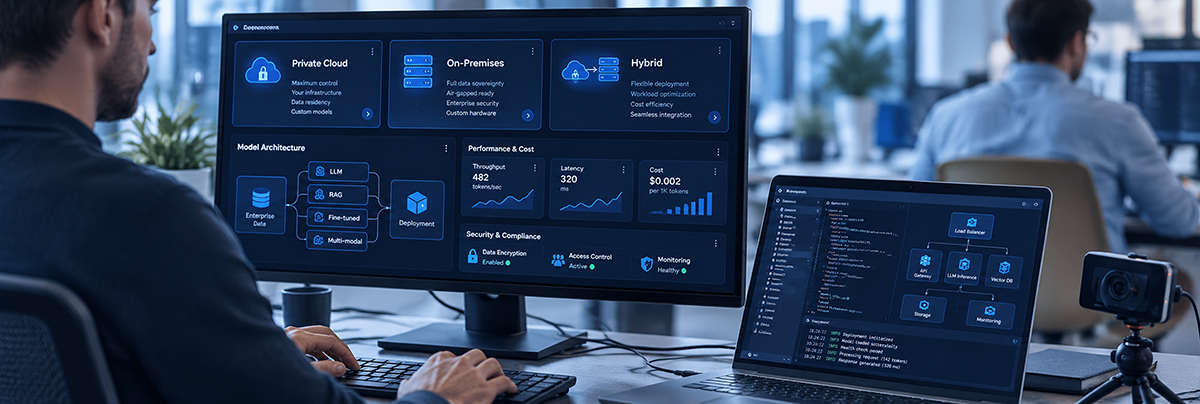
Build an LLM Foundation Ready for Enterprise Workloads
We develop enterprise LLM solutions aligned with your data, workloads, security requirements, and deployment environment, giving your AI initiatives a reliable model layer built for production.
- Select models for workload and cost requirements
- Fine-tune models on proprietary business data
- Deploy with security and data residency controls
- Validate performance before production deployment
Why Enterprises Choose EWW for LLM Development
Enterprise LLM development requires more than access to leading models. We bring model expertise, enterprise data, secure deployment, and production engineering into one delivery approach.
Model Agnostic by Design
Our team follows a model-agnostic approach to assess enterprise requirements upfront. Recommendations remain aligned with task complexity, quality, latency, cost, and deployment constraints.
Proprietary Data Comes First
Enterprise data plays a critical role in effective LLM behavior. Our fine-tuning approach uses proprietary documents, terminology, and workflows to adapt models beyond generic, off-the-shelf foundation models.
Enterprise Control at Every Layer
Enterprise LLM development follows workload-specific control requirements. Our LLM architecture supports cloud, private VPC, and on-prem environments, chosen by your data residency, sovereignty and security needs.
Production Ready Before Going Live
Production readiness is a release requirement, not a final check. Our LLM teams treat evaluation, red-teaming, and guardrails as engineering requirements before critical workflows depend on them.
Designed for Wider AI Stack
The LLM foundation is part of a wider AI architecture. Our engineers design the model layer to work with Generative AI Development, RAG, copilots, AI agents, enterprise applications, and existing data systems.
Monitored After Launch
LLM delivery continues after launch. Our team monitors enterprise LLM cost, latency and output quality, then optimizes, retunes or retrains the model or architecture when performance drops.
Our Recent Projects
We always believe in serving our clients with best and effective solutions that enables them to get over the startup challenges. Here we’ve showcased a few applications built by our experts based on client requirements.
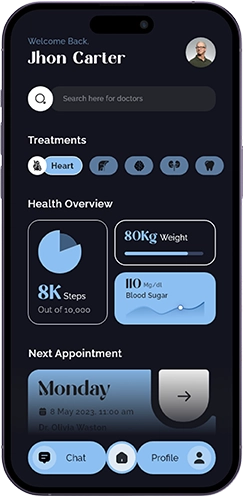
AI Virtual Health Assistant
We developed an AI-powered virtual health assistant for a hospital chain to help doctors and staff collect patient information efficiently.
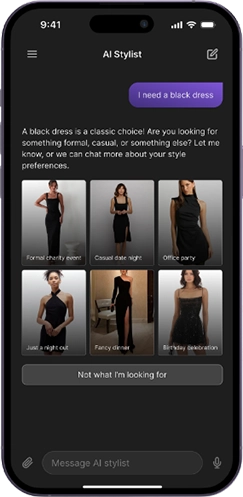
An AI-Driven Visual Product
Our team created and advanced visual product search platform for an eCommece brand leveraging AI-based solutions.
Data Residency and Model Governance
Where your model runs, what data shapes it, and how its activity is tracked are compliance questions before they become technical ones.
Data Residency & Sovereign Hosting
Training and inference data remains within the regions or infrastructure required to comply with data residency, sovereignty, and regulatory requirements.
Training Data Governance
Every fine-tuning dataset is documented, versioned, and access-controlled, so you can easily trace which data shaped your enterprise model and its behavior.
Model Access & Audit Logging
Every prompt and completion is logged and attributable, with audit records aligned with your industry’s regulatory and governance requirements.
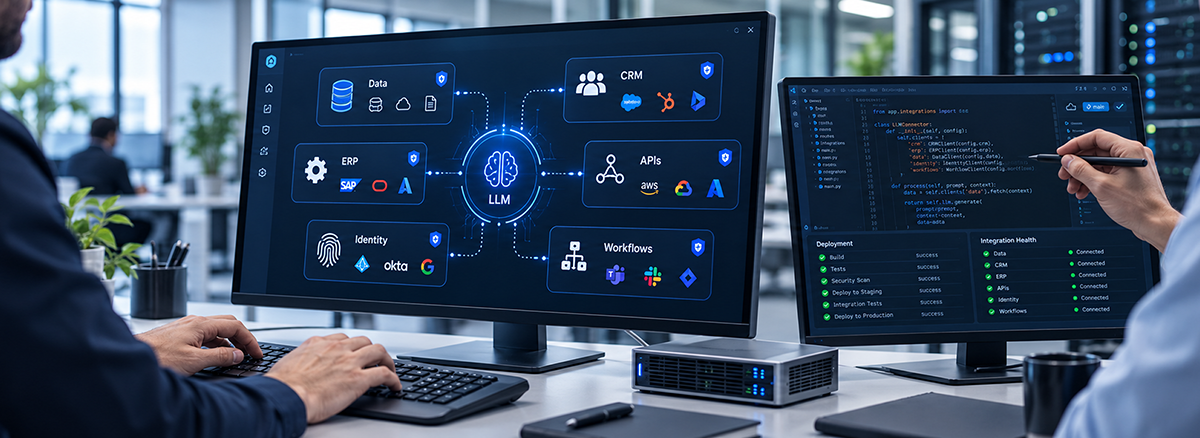
What Your LLM Connects To
An LLM sitting outside your stack has limited business value. Our AI Integration services connect enterprise LLMs with the systems, data, tools, identity controls, and workflows your teams already depend on.
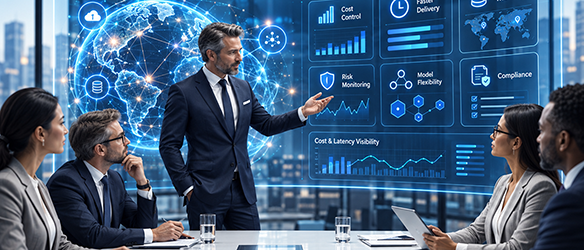
What Changes for Leadership vs. What Changes for the Team Building on It
A well-built enterprise LLM layer adds a different value for leadership and the teams building on it. Both perspectives hold an equal importance when the model is the centerpoint for foundation.
 For Leadership
|
|---|
|
|
 For the Team Building On It
|
|---|
|
|
Build Enterprise AI on a Foundation You Can Control
You don’t need another generic AI model; you need an LLM foundation aligned with your data, workloads, security requirements, and business goals. Build enterprise AI with greater control over performance, deployment, and governance.
- Improve model performance on business-specific workloads
- Keep sensitive data and model access under control
- Scale AI initiatives with a production-ready foundation
Enterprise LLM Development Pricing
Three starting points, scoped to how much of the model layer you need us to own.
Model Evaluation & Pilot
Validate the right model before committing to production
- Enterprise workload mapping and model benchmarking
- Small-scale fine-tuning proof of concept
- Evaluation report against your use cases
- 3–5 week engagement
Production Fine-Tune & Deploy
Turn a validated model into a production-ready enterprise LLM
- Full fine-tuning on your proprietary data
- Deployment to cloud, VPC or on-prem
- Guardrails, evaluation harness, and production monitoring
- API access for your teams to build on
Enterprise Multi-Model Program
Build a governed model layer across enterprise workloads
- Multi-model routing across enterprise use cases
- Shared governance and access control
- Compliance mapped to your industry requirements
- Centralized model oversight across deployments
| Pricing Factor | What Drives This Number? |
|---|---|
| Model & workload scope | Number and complexity of LLM workloads |
| Fine-tuning requirements | Data volume and tuning complexity |
| Deployment environment | Cloud, VPC, or on-premise setup |
| Evaluation depth | Number of tests, benchmarks, and checks |
| Governance & compliance | Industry and regulatory requirements |
| Integration complexity | Systems, APIs, and workflows involved |
| Engineering involvement | Scope of embedded engineering support |
| Ongoing optimization | Monitoring and model improvement needs |
The Enterprise LLM Tech Stack We Work With
We work across leading foundation models, AI frameworks, cloud platforms, deployment infrastructure, and enterprise security technologies.
Foundation Model Providers
- OpenAI
- Anthropic
- Google Gemini
- Meta Llama
- Mistral
- Qwen
- DeepSeek
LLM Frameworks & Orchestration
- LangChain
- LangGraph
- LlamaIndex
- Semantic Kernel
Fine-Tuning & Training
- Hugging Face
- LoRA
- PEFT
- PyTorch
- Ray
Cloud & Model Platforms
- AWS Bedrock
- Microsoft Foundry (Azure OpenAI)
- Gemini Enterprise Agent Platform (formerly Google Vertex AI)
Model Serving & Infrastructure
- vLLM
- Kubernetes
- NVIDIA CUDA
- On-Premises GPU Clusters
Evaluation & Guardrails
- Promptfoo
- Ragas
- Custom Evaluation Frameworks
- Adversarial Red Teaming
RAG & Vector Databases
- Pinecone
- Weaviate
- pgvector
- Milvus
LLMOps & Observability
- MLflow
- LangSmith
- Langfuse
- Weights & Biases
- Arize
Security & Enterprise Access
- SSO/SAML
- RBAC
- Audit Logging
- Encryption
- Data Residency Controls
How We Build Your Enterprise LLM
A right-size-first process. We match the model to the workload before fine-tuning or deployment, then validate its performance through real enterprise use.
Define Enterprise Workloads
We map each enterprise workload that runs on a model and define the accuracy, response speed, context, and reliability requirements before choosing a model for each use case.
Select the Right Model
Our team evaluates open-weight and proprietary model families against every mapped workload, then recommends the best model based on accuracy, quality, cost, context, and latency needs, not trends.
Prepare Data for Auditing
We audit, clean, and structure your proprietary data before any fine-tuning, with checks for relevance, consistency, labeling, duplication, sensitive information, and training readiness.
Fine-tune & Adapt the Model
We fine-tune the selected model on your documents, tickets, domain terminology, and business examples so its outputs reflect how your enterprise actually speaks and works.
Validate Model Performance
The model is benchmarked against defined performance targets, then we test real edge cases and adversarial prompts to identify hallucinations, unsafe outputs, and reliability gaps before production release.
Deploy to Your Environment
We deploy the model to your chosen environment, whether that is a public cloud, private VPC, or fully on-prem setup, based on the data residency and compliance rules your enterprise must meet.
Test with Real Workloads
Our LLM experts run a focused pilot with real users and workloads, then measure accuracy, latency, and cost against production targets defined during discovery and model selection.
Refine Model Performance
We use pilot feedback to optimize the model, close performance gaps, then establish guardrails and acceptance criteria before the LLM moves into broader production use across your teams.
Handover or Managed Support
Your team receives the model with monitoring dashboards and full documentation, or our team continues to manage performance, updates, and operational needs under an ongoing plan.
Add-On Services Our Clients Pair with Enterprise LLM Development
The model layer is the foundation. These are the systems EWW builds on top of it.
AI Copilot Development
Enterprise teams need quick access and support for the AI tools they use in their daily workflow, not in a separate chat window. We engineer copilots considering your LLM, data, and workflow to support better decisions and streamline tasks.
RAG and Enterprise Knowledge
Enterprise LLMs rely on trusted business context to deliver answers. We build retrieval infrastructure that grounds every answer considering your current company documents and data.
AI Governance & Compliance
Enterprise AI needs complete control over the regions, risks, and regulations once it touches production and real users. We build regional compliance, audit trails, and governance frameworks across your entire AI system.
Applied AI & Data Solutions
Not every problem can be resolved with the same language model. Our LLM experts build bounded machine learning solutions as per the specific enterprise use case, such as prediction, vision, process automation, and model agnostic.
Frequently Asked Questions
An enterprise LLM is the underlying model layer selected, fine-tuned and secured for a company’s own data, workflows and compliance requirements. An AI copilot is a separate application built on top of that model, embedded inside a tool like a CRM or helpdesk to assist one specific workflow.
An enterprise LLM is a large language model selected, customized, deployed, and secured particularly for a company’s own data, workflows and compliance requirements. As compared to generic API, it is built to support required business needs with effective control over its data and deployment environment.
An enterprise LLM provides the model layer for reasoning and language-based tasks. Agentic AI is often referred to as the orchestration layer, using that reasoning to complete multi-step, autonomous actions across tools with limited human checkpoints.
Fine-tuning changes the model’s weights through additional training to enhance its performance across a set of tasks, formats and domain language. RAG leaves the model unchanged and retrieves relevant documents at query time to ground its answers. Many enterprise deployments use both.
It depends on your data residency, security, compliance, cost and operational needs. Cloud hosting is fastest to deploy, private VPC deployment offers strong network isolation, and on-premises or sovereign environments support stricter infrastructure and residency controls, such as government or defense.
Enterprise LLM development typically takes 3 to 6 months to develop a production-ready MVP with guardrails and monitoring. A complex enterprise LLM development project can take 12 months or more. Actual timelines vary based on the project scope, data readiness, third-party integrations, and hosting environment.
Enterprise LLM development costs typically range from $50,000 to $150,000 or more. The cost depends on the model choice, fine-tuning scope, and hosting environment. We scope the cost after a short discovery call rather than quoting blindly, since a right-sized smaller model can cost far less to run than a flagship model used by default.
Yes. We track and version-control every fine-tuning dataset, and apply role-based access control to protect training data throughout. We define the hosting environment and data handling controls around your compliance requirements, along with regional residency and access policies.